In this tutorial, you will explore the Semarchy Data Platform Extension — a Visual Studio Code integration that enables you to design, build, and deploy Semarchy Data Products directly from your local environment.
Through a guided, hands-on exercise, you will learn how to create and configure a complete Employee Data Product, discovering how the extension supports every stage of model design — from defining entities, attributes, and relationships to implementing enrichers, validations, match rules, and survivorship strategies.
What you'll learn
- Install and configure the Semarchy Data Platform extension in Visual Studio Code.
- Create a data project, a Data Product package, and a Data Product folder to organize your design files.
- Design the Employee Data Product, including its logical data model, entities, attributes, and relationships.
- Define Lists of Values to standardize data.
- Implement fuzzy matching, data enrichment, validation, and survivorship rules.
- Generate application components for your end-user interface.
- Build and deploy your Data Product to the shared training environment and import real data.
By the end of this tutorial, you will understand how a logical data model and an MDM web application are assembled within a Data Product, and how the complete Data Product is validated, built, and deployed.
Before you start
Before starting, make sure you have:
- Installed Visual Studio Code (latest version recommended).
- Downloaded and installed the Semarchy Data Platform extension from the Visual Studio Marketplace
- Access credentials for your particular Semarchy Saas instance.
- Basic understanding of:
- Relational data concepts (tables, keys, relationships)
- The purpose of Master Data Management (MDM)
- YAML syntax (for .seml files)
Additional setup information can also be found in the official documentation: Set up your design environment
Please, click on the link below to download the required resources, including the images and datasets used within this tutorial.
Download the tutorial resources
All steps are designed to be self-contained, guiding you through the process even if you have limited prior experience with Semarchy Data Platform.
The Employee Logical Model represents a simplified but realistic master data domain centered around employees and departments within an organization.
It helps you experience how to manage fuzzy-matched entities, relationships, and hierarchies in practice.
Model Overview
The model contains two core entities:
- Department
- A Basic Entity, holding structural information about the organization (e.g., department name, code).
- Acts as a reference entity linked to employees.
- Employee
- A Fuzzy-Matched Entity, containing employee master records from multiple source systems (e.g., HR, Payroll, ATS).
- Designed to handle duplicates, data enrichment, and survivorship logic.
In addition, the model includes:
- Two Lists of Values (LOVs):
- Salutations (Mr, Mrs, Ms, etc.)
- Subsidiaries (ACME_APAC, ACME_EU, ACME_US)
Business Context
Imagine a multinational company consolidating employee data coming from several systems:
- HR system (HR) manages hiring and department assignments.
- Applicant Tracking System (ATS) tracks candidates and onboarding details.
- Payroll (PAY) manages compensation data.
Each of these systems may contain overlapping or conflicting records — for example, the same person entered twice with slightly different spellings or formatting ("Jon Smith" vs. "John Smith").
Using the Employee Logical Model, you will learn how to:
- Cleans and standardizes attributes (via enrichers),
- Identifies and merges duplicate records (via fuzzy matching),
- Consolidates the best data into golden records (via survivorship rules),
- Publishes the resulting single source of truth to the organization.
Learning Objective
By the end of the labs, you will have built a fully functional Employee Data Product, capable of:
- Consolidating data from multiple sources,
- Automatically standardizing, matching, and merging records,
- Providing a clean, user-friendly interface to view and manage master data,
- Demonstrating end-to-end governance from design to deployment.
This practical exercise will help you not only learn how to model, but also think like an MDM designer — structuring data for real-world enterprise use cases.
In this first chapter, you'll install the Semarchy Data Platform Extension and set up the VS Code workspace that represents your data project. In SDP the workspace is the top-level organizational unit and can contain one or more Data Product packages.
This workspace will be the starting point for all the Data Product design work you'll do in the next chapters.
Install the Semarchy Data Platform Extension
You can skip this task if the extension is already installed in your VS Code.
- Open Visual Studio Code.
- Go to Extensions (Ctrl+Shift+X).

- Search for Semarchy Data Platform.
- Select the official extension and click Install.

- Once installed, you should see the Semarchy Data Platform icon appear in the left activity bar — this confirms that the extension is ready to use.
Initiate the Data Product Package
You will create a Data Product package folder named employee-training-project. A Data Product package is the organizational unit that contains the structure, design files, and supporting resources required to build and deploy one Data Product.
- Find a suitable location on your computer and, using File Explorer, create a folder named employee-training-project.
- In VS Code, select File → Open Folder... and open employee-training-project.
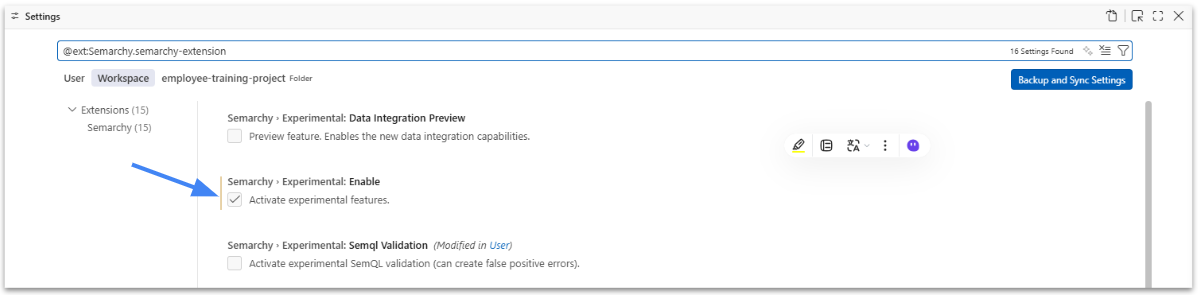
- Before initializing the Data Product package, make sure that the Semarchy experimental features are enabled for the workspace. Open the VS Code Settings, select the Workspace tab, and locate the Semarchy extension settings. Under Experimental, enable Experimental: Enable.
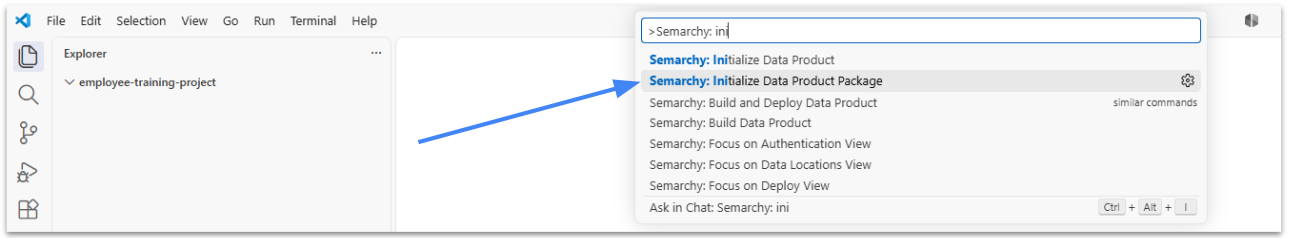
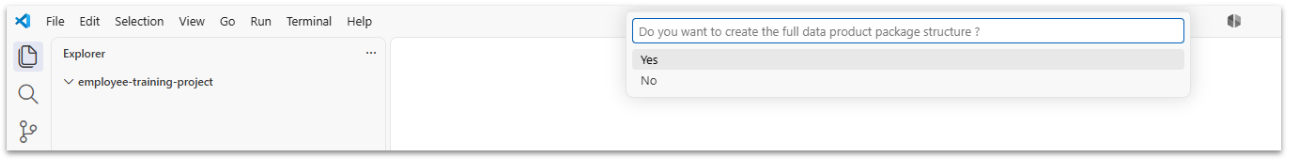
- In the View menu, launch Command Palette (Ctrl+Shift+P). Search for and run: Semarchy: Initialize Data Product Package. You will be asked whether you want to create the full project structure — click Yes.
- Expand your project tree in the Explorer view to verify that the configuration files and the src directory are now visible.
Create the Workspace
- In the File menu, select Add Folder To Workspace... and choose the employee-training-project folder.
- Save the workspace: In the File menu, select Save Workspace As..., and rename it to employee-training-project.code-workspace.
Verify the Project Structure
Let's take a look at the result. Your Explorer view should now look like this:
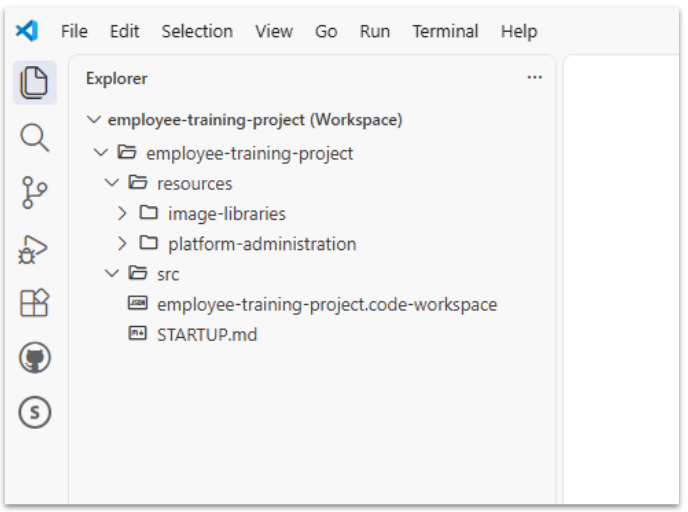
In the bottom-right corner, you may see the message: "Configuration is configured correctly".

At this point, you have created the data project and initialized its first Data Product package. The next step is to initialize the Employee Data Product under the package's src folder.
In this chapter, you will initialize the Employee Data Product. Its Data Product folder will contain the logical data model, certification rules, application definitions, and the Data Product profile used for technical configuration.
You will use the workspace set up in the previous chapter.
Initialize the Data Product
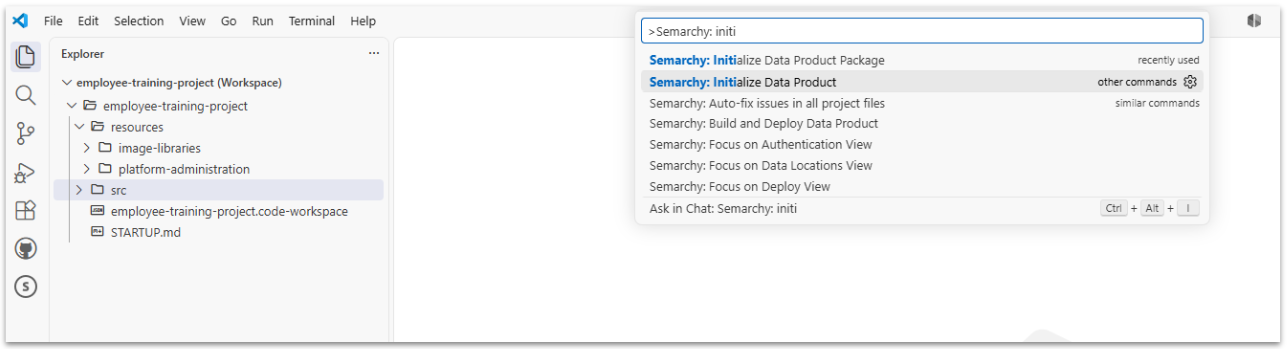
- Create a new Data Product named Employee under the src folder. From the View → Command Palette menu type Semarchy: Initialize Data Product
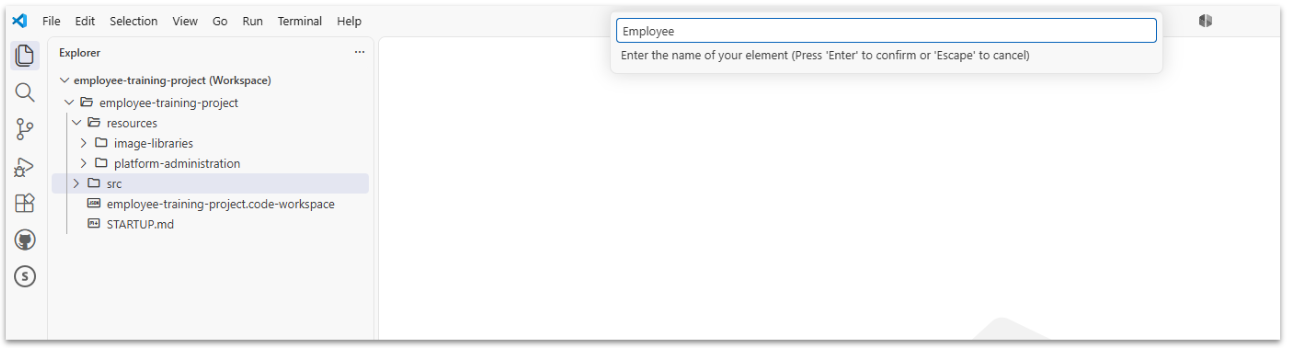
- Give a name to your Model, Employee, in this example, and press Enter:
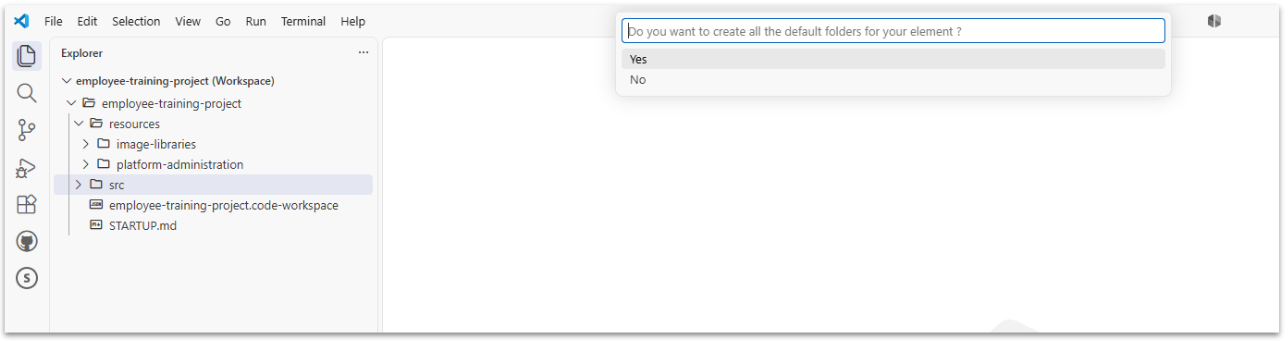
- When prompted, choose Yes to create all default folders.
Explore Data Product Components and Default Folders
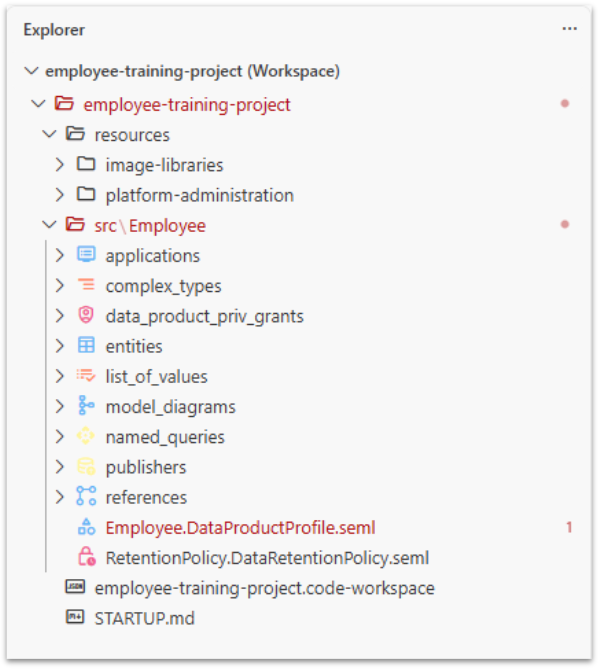
Observe what folders have been created automatically under the Employee folder.
Review the Application Definition
Expand the applications folder and open the file DefaultApplication.Application.seml
. This file was automatically generated when you created the Data Product.
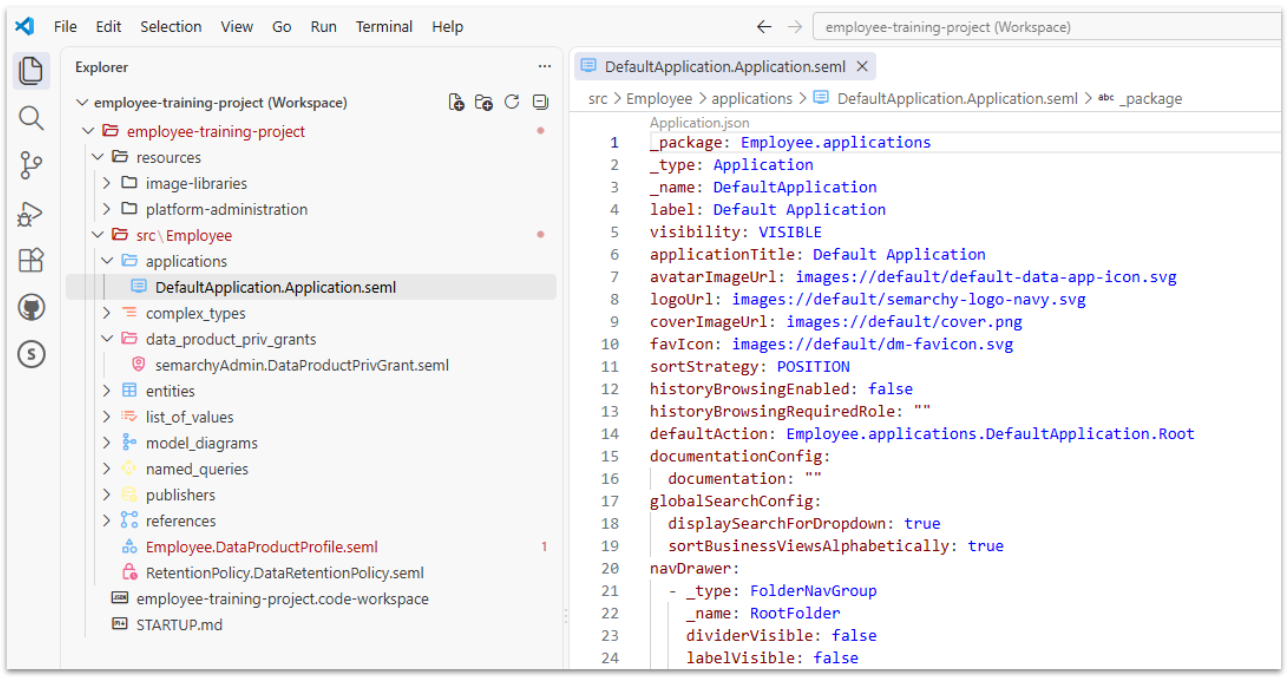
Update the Label and applicationTitle properties — this will be the name of your application in the Data Platform. Then, save your changes and close the file.
label: Employee Application
applicationTitle: Employee Application
Understand the Data Product Profile and Privilege Grants
Before you start creating entities, it's essential to understand the SDP Data Product structure and the role of its required profile.
Each Data Product includes key design files that define its technical configuration and security.
Here, you'll look at two of them — Employee.DataProductProfile.seml (the Data Product profile) and semarchyAdmin.DataProductPrivGrant.seml (the access permissions).
- Open the file Employee.DataProductProfile.seml:
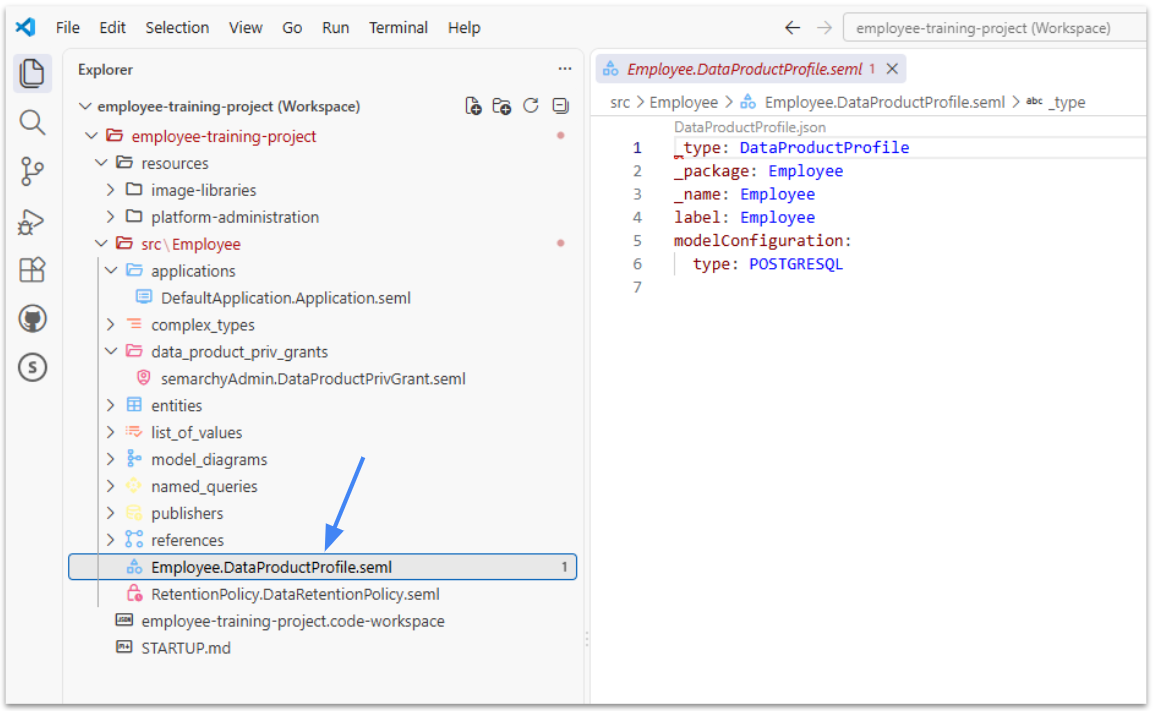
The Data Product profile defines the technical environment used by the Data Product and provides configuration settings required by other design objects.
Every Data Product requires exactly one Data Product profile, stored at the root of the Data Product folder.
When you later build or deploy the Data Product, the extension uses this profile to:
- Recognize the Data Product name and configuration,
- Compile all referenced components (entities, LOVs, validations, etc.),
- Generate the appropriate SQL and metadata for the target platform (PostgreSQL).
💡Tip: Customizing the Data Product Header
At this stage, you can already enrich the header with a short description.
This does not affect deployment or runtime behavior, but it helps document the purpose of the Data Product directly in the code. For example:
_type: DataProductProfile
_package: Employee
_name: Employee
label: Employee
description: "A Data Product consolidating employee and department data from multiple business systems (HR, ATS, Payroll)."
modelConfiguration:
  type: POSTGRESQL
Adding a description makes the Data Product easier to understand when browsing the project or collaborating with others, especially in environments with multiple Data Products. You'll revisit this metadata later in the Build and Deploy phase, where its real impact becomes visible.
- Now if you look at the Problems tab in VS Code, you may see a few problems — this is expected at this stage, as the Data Product doesn't yet contain any entities or attributes.
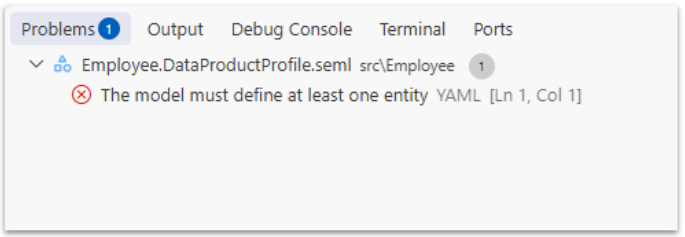
You'll address these in the next chapters as the Data Product takes shape.
- When you create a new Data Product, the Semarchy extension automatically generates a Data Product Privilege Grant file semarchyAdmin.DataProductPrivGrant.seml located in the data_product_priv_grants folder:
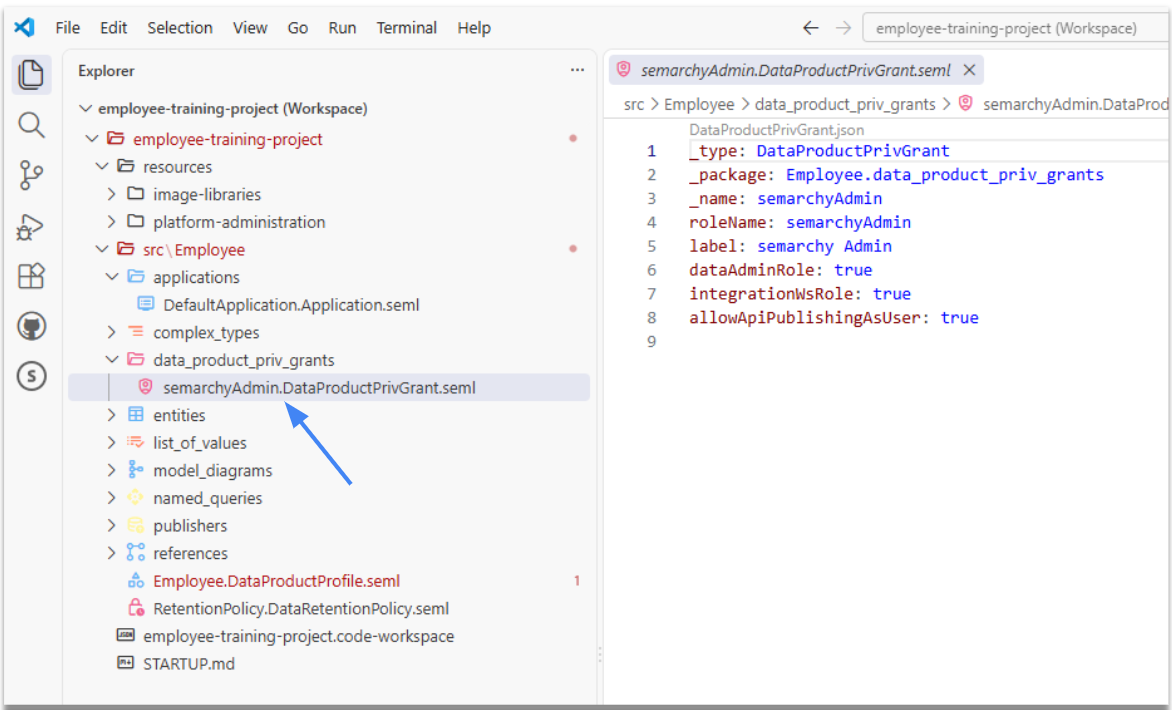
This file defines who has access to the Data Product and what they are allowed to do once it's deployed to the Semarchy Data Platform.
The default file, semarchyAdmin.DataProductPrivGrant.seml, is created automatically and grants full privileges to the Semarchy Administrator account.
This ensures that once your Data Product is deployed, the system administrator can access it without restrictions.
You'll explore these aspects later in the course.
Create the Department Entity
In this section, you'll create your first business entity — Department.
This entity will store the list of departments within the company and later serve as a reference for the Employee entity.
- In Visual Studio Code, open your workspace (employee-training-project.code-workspace) if it isn't already open.
- Open the Command Palette (View → Command Palette) and run Semarchy: Create Entity.

- Enter the entity name: Department.

- When prompted for a location, choose the folder src/Employee/entities.
- When asked to create the default folder structure, choose Yes.

- In the next prompt, select Basic Entity as the entity type.

The extension automatically generates a complete folder structure for your new entity, including design files for attributes, enrichers, validations, and more.
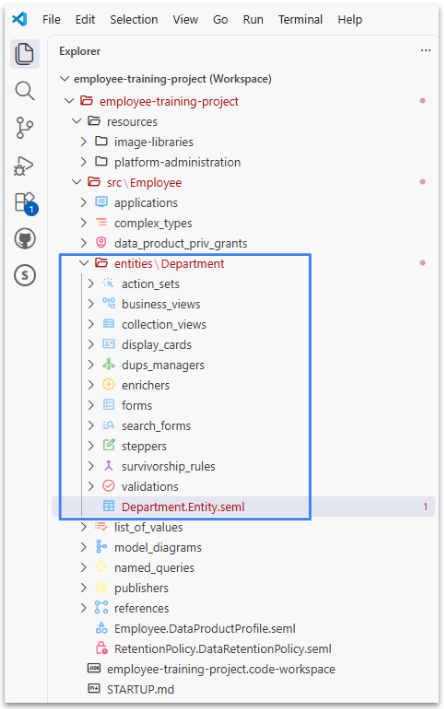
Add and Configure Attributes
Let's configure some attributes of the Department entity. Here is the description of them:
Attribute | Datatype | Mandatory | Notes |
DepartmentID | String (20) | Yes | ID is set manually |
DepartmentName | String (128) | Yes | Name of the department |
DepartmentDescription | String (4000) | No | Description of this department |
- Add DepartmentID Attribute.
Every new entity starts with a single default attribute, typically named after the entity (for example, DepartmentID), and defined as a LongInteger.

Let's adjust it to follow the desired format.
- Open the Department.Entity.seml file.
- Locate the section defining the primary key (
DepartmentID). - Change the data type from
LongIntegertoString. - Set its length to
20. - Remove the
precisionproperty (if present). - Under
SourceIDGeneration, change themodetoMANUAL.
Your ID will now be manually defined, giving you full control over how departments are identified.
attributes:
  - _type: EntityAttribute
    _name: DepartmentID
    label: Department ID
    physicalName: DEPARTMENT_ID
    dataType: String
    length: 20
    mandatory: true
    searchable: true
sourceIdGeneration:
  mode: MANUAL
primaryKey: Employee.entities.Department.Department.DepartmentID
- Add DepartmentName Attribute.
- Place your cursor below the last attribute in the attributes list.
- Start typing
- _type:— VS Code will suggest the attribute typeEntityAttribute. - Continue adding the remaining properties with the following values:
Property | Value |
_name | DepartmentName |
label | Department Name |
physicalName | DEPARTMENT_NAME |
dataType | String |
length | 128 |
mandatory | true |
searchable | true |
mandatoryValidationScope | PRE_CONSO |
Your entity now has two attributes:
DepartmentID— a manually set identifier,DepartmentName— the department's business name.
You can collapse each attribute section by clicking the arrow next to its _type for easier navigation in the editor.

- Add DepartmentDescription Attribute.
- Like for the DepartmentName attribute, start typing
- _type:— VS Code will suggest the attribute typeEntityAttribute. - Continue adding the remaining properties with the following values:
Property | Value |
_name | DepartmentDescription |
label | Department Description |
physicalName | DEPARTMENT_DESCRIPTION |
dataType | String |
length | 4000 |
mandatory | false |
searchable | true |

You've successfully created and configured your first entity — Department. Don't forget to save the file.
Add a Unique Key to the Department Entity
Although DepartmentID already uniquely identifies each department as its primary key, nothing yet prevents two departments from being created with the same DepartmentName. A unique key lets you enforce that additional constraint.
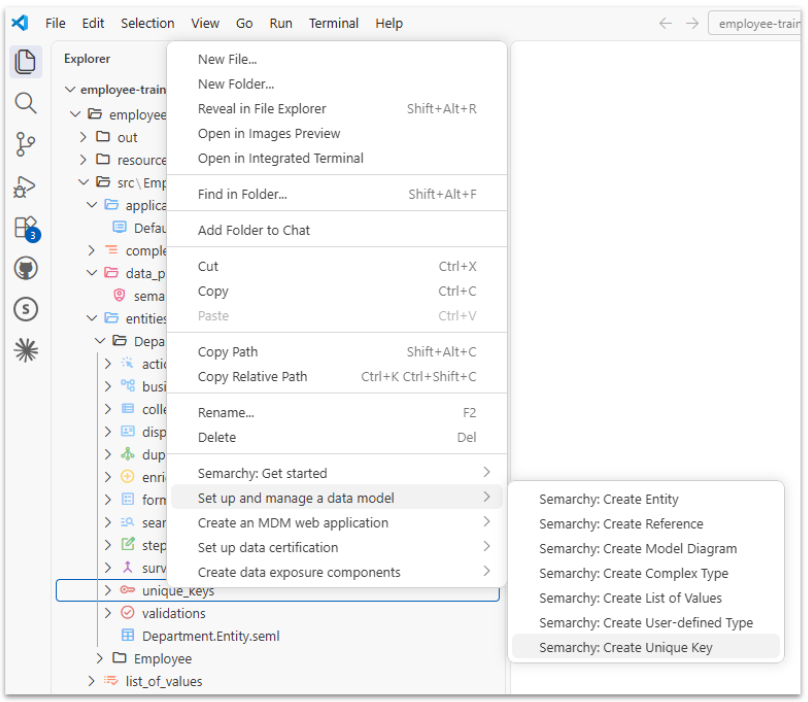
- In the Department entity's folder, create a new folder named
unique_keys. - Right-click the
unique_keysfolder and run Set up and manage a data model -> Semarchy: Create Unique Key.
- Enter the name:
DepartmentNameUniqueKey. - Complete the following properties:
_name: DepartmentNameUniqueKey
_type: UniqueKey
_package: Employee.entities.Department.unique_keys
entity: Employee.entities.Department.Department
label: "Department Name Unique Key"
keyAttributes:
    - attribute: Employee.entities.Department.Department.DepartmentName
validationLabel: "A department with this name already exists."
validationScope: PRE_CONSO
What this does: keyAttributes lists the attributes that together must be unique for every Department record — here, just DepartmentName. validationScope - PRE_CONSO - checks the constraint before consolidation, on incoming records.
Save and close the file.
Define a List of Values
- Creating the "Salutations" LOV
Let's start with a small LOV for employee titles.
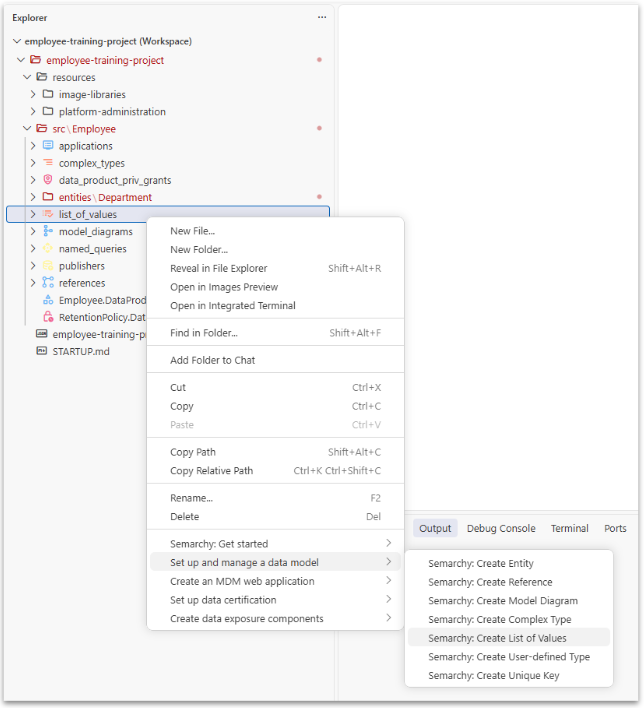
- In the Explorer panel, expand your model folder: src/Employee/list_of_values
- Right-click the folder (or use the Command Palette Semarchy: Create List of Values) and run: Set up and manage a data model -> Semarchy: Create List of Values
- Enter the name: Salutations. A new file Salutations.LOVType.seml is created. Open it.

- Fill the properties :
label : Salutations;length: 8 - Add the following entries
lovValues:
Code | Label |
Dr | Dr |
Mr | Mr |
Mrs | Mrs |
Miss | Miss |

- Save and close the file.
2. Creating the "Subsidiaries" LOV
Here, you'll create a second LOV representing the organization's subsidiaries.
Repeat the same steps:
- Right-click
list_of_values; - Run Semarchy: Create List of Values;
- Name it
Subsidiaries; - Open the generated file;
- Add the entries below:
Code | Label |
ACME_APAC | ACME_APAC |
ACME_EU | ACME_EU |
ACME_US | ACME_US |
Your LOV file should look like:
_package: Employee.list_of_values
_name: Subsidiaries
_type: LOVType
label: Subsidiaries
length: 16
lovValues:
  - label: ACME_APAC
    code: ACME_APAC
  - label: ACME_EU
    code: ACME_EU
  - label: ACME_US
    code: ACME_US
3. Validating Your Work
Once you save both LOV files:
- No additional errors should appear in the Problems tab.
- You will be able to reference these LOVs in the next chapter when you build the Employee entity attributes.

Create the Employee Entity
In this section, you'll create your core business entity: Employee.
Unlike the Department entity you built earlier, Employee will be a Fuzzy-Matched Entity, meaning that DM will automatically detect duplicates and consolidate them into golden records.
You will also:
- Add essential attributes ;
- Connect Employee to Department with a reference relationship;
- Use the LOVs created earlier.
Let's create the Employee Entity.
- Open the Command Palette and search for: Semarchy: Create Entity
- Choose the folder: src/Employee/entities
- Enter the name: Employee
- When prompted to create the folder structure, click Yes
- Choose Fuzzy-Matched as the entity type
You now have an empty Employee entity ready to be populated with attributes and rules.
Expand the Employee folder. You'll see a set of default subfolders similar to the Department entity (attributes, validations, enrichers, steppers, and so on), which will be filled as you progress through later chapters.

Open the file Employee.Entity.seml. Let's observe the key default properties of a Fuzzy-Matched Entity and how they differ from a Basic Entity like Department.

Adjusting Default Properties of the Employee Entity
Before adding business attributes, you will first adjust the default configuration of the Fuzzy-Matched Employee entity.
The goal is to align your entity with recommended MDM settings and ensure it behaves correctly within the mastering process.
- At the top of the file, you will find the following fields:
description: ""
documentation: ""
The property description is intended for short, functional notes about the entity. The property documentation can include larger, technical or business explanations.
For now, leave them blank. You will fill them in later if needed, once your model is complete. It's a good practice to keep these fields present even if temporarily empty.
- Note that goldenIdGeneration is already correctly generated by default. It is configured to use a
SEQUENCEstarting at1, which ensures that each golden record receives a unique and automatically incremented identifier. No change is required here — simply verify the configuration and leave it as it is:
goldenIdGeneration:
  mode: SEQUENCE
startWith: 1- Switch source ID generation to MANUAL. This allows IDs from source systems to be preserved during mastering.
sourceIdGeneration:
mode: MANUAL- For proper auditability of employee records, activate history for both golden and master records. These settings allow you to track how both mastered records and golden records evolve over time.
historizeGolden: true
historizeMaster: true- Make sure users can add or update employee records through the Semarchy application UI.
dataEntryAllowed: trueAfter updating the default properties, your Employee.Entity.seml file should match the sample configuration below with proper metadata, ID generation settings, history tracking, etc.

Your Employee entity is now ready for the next chapter, where you will add all business-relevant attributes.
Define Attributes
At this stage, only one attribute: a default primary key (EmployeeID) is present.
- Take a look at the default EmployeeID attribute, already configured as follows:
- _type: EntityAttribute
    _name: EmployeeID
    physicalName: EMPLOYEE_ID
    dataType: LongInteger
    label: Employee ID
    mandatory: true
    precision: 38
searchable: true - Next, you'll add the business attributes for the Employee entity. Here is their description.
Attribute | Datatype | Mandatory | Notes |
EmployeeID | LongInteger | Yes | ID is set manually |
FirstName | String (128) | Yes | |
LastName | String (128) | Yes | |
HireDate | Date | Yes | The date the employee was hired |
Subsidiary | List of values | Yes | Uses Subsidiaries LOV |
Salutation | List of values | No | Uses Salutations LOV |
Title | String(128) | No | Job title |
String(500) | No | ||
IsContractor | Boolean | No | Optional flag |
Picture | Binary | No | Will hold the employee picture |
EndDate | Date | No | End of employment |
Phone | String(128) | No |
Here is the recommended SEML structure for several key attributes:
# First Name
  - _name: FirstName
    _type: EntityAttribute
    label: First Name
    physicalName: FIRST_NAME
    dataType: String
    length: 128
    mandatory: true
    mandatoryValidationScope: PRE_CONSO
    searchable: true
# Last Name
  - _name: LastName
    _type: EntityAttribute
    label: Last Name
    physicalName: LAST_NAME
    dataType: String
    length: 128
    mandatory: true
    mandatoryValidationScope: PRE_CONSO
    searchable: true
# Salutation (LOV)
  - _name: Salutation
    _type: EntityAttribute
    label: Salutation
    physicalName: SALUTATION
    dataType: Employee.list_of_values.Salutations
    lovValidationScope: PRE_CONSO
    mandatory: false
# Subsidiary (LOV)
  - _name: Subsidiary
    _type: EntityAttribute
    label: Subsidiary
    physicalName: SUBSIDIARY
    dataType: Employee.list_of_values.Subsidiaries
    lovValidationScope: PRE_CONSO
    mandatory: true
    mandatoryValidationScope: PRE_CONSO
Continue adding the remaining attributes:
# Title
  - _name: Title
    _type: EntityAttribute
    label: Title
    physicalName: TITLE
    dataType: String
    length: 128
    mandatory: false
# Hire Date
  - _name: HireDate
    _type: EntityAttribute
    label: Hire Date
    physicalName: HIRE_DATE
    dataType: Date
    mandatory: true
    mandatoryValidationScope: PRE_CONSO
# End Date
  - _name: EndDate
    _type: EntityAttribute
    label: End Date
    physicalName: END_DATE
    dataType: Date
    mandatory: false
# Contractor Flag
  - _name: IsContractor
    _type: EntityAttribute
    label: Is Contractor
    physicalName: IS_CONTRACTOR
    dataType: Boolean
    mandatory: false
# Email
  - _name: Email
    _type: EntityAttribute
    label: Email
    physicalName: EMAIL
    dataType: String
    length: 500
    mandatory: false
# Phone
  - _name: Phone
    _type: EntityAttribute
    label: Phone
    physicalName: PHONE
    dataType: String
    length: 128
    mandatory: false
# Picture
  - _name: Picture
    _type: EntityAttribute
    label: Picture
    physicalName: PICTURE
    dataType: Binary
mandatory: false Establish the Relationship
Now you'll create the relationship that connects each employee to exactly one department.
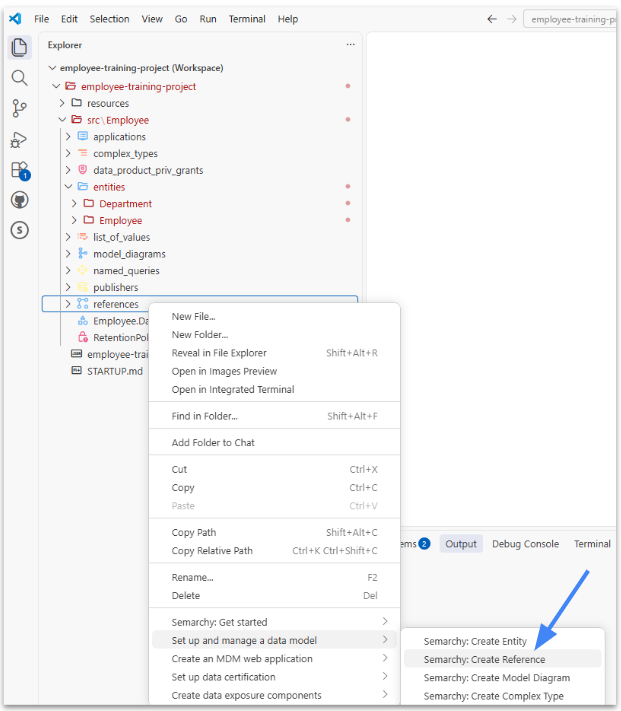
- In the references folder, run Set up and manage data model -> Semarchy: Create Reference:
- Name the reference: EmployeeBelongsToDepartment:

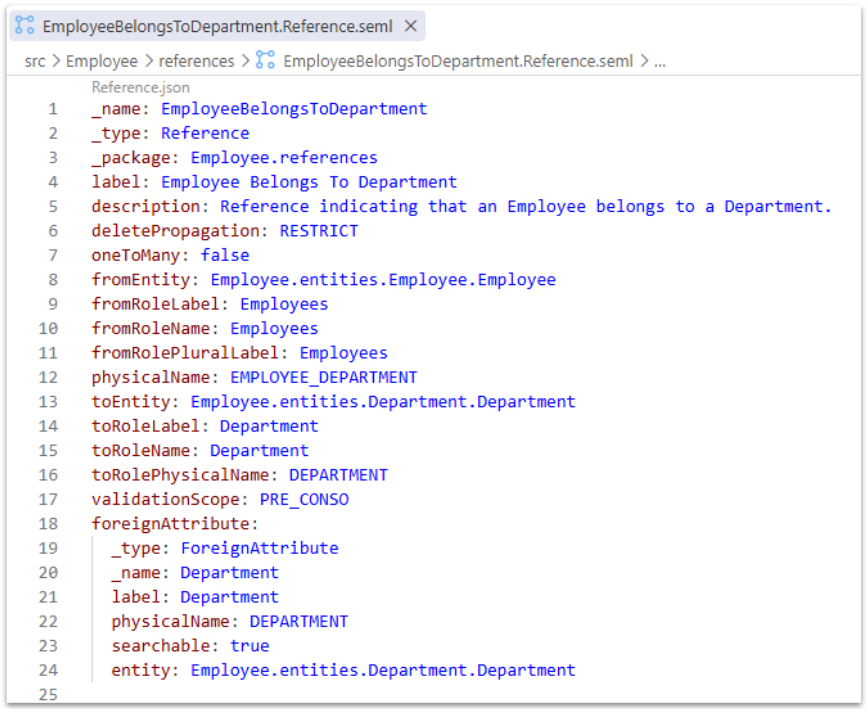
- Open the file EmployeeBelongsToDepartment.Reference.seml and observe the default structure:

- Fill the core properties:
label: Employee Belongs To Department
description: Reference indicating that an Employee belongs to a Department.
deletePropagation: RESTRICT
oneToMany: false
fromEntity: Employee.entities.Employee.Employee
fromRoleLabel: Employees
fromRoleName: Employees
fromRolePluralLabel: Employees
physicalName: EMPLOYEE_DEPARTMENT
toEntity: Employee.entities.Department.Department
toRoleLabel: Department
toRoleName: Department
toRolePhysicalName: DEPARTMENT
validationScope: PRE_CONSO - Add Foreign Attribute for UI convenience. This makes the department name visible directly in the Employee view.
foreignAttribute:
  _type: ForeignAttribute
  _name: Department
  label: Department
  physicalName: DEPARTMENT
  searchable: true
entity: Employee.entities.Department.DepartmentNow your reference file should look like this:
- After saving:
- Most red squiggles should disappear.
- Warnings about Match Rules and Display Cards are expected (these will be added later in the matching chapter).

Result
Your Employee entity is now fully defined and structurally complete, with:
- All required business attributes;
- Proper use of LOVs;
- A clean, relational link to the Department entity;
This entity will serve as the foundation for enrichment, validation, matching, and survivorship logic in the chapters that follow.
In this chapter, you will standardize employee names and prepare them for fuzzy matching. You will clean and properly format both FirstName and LastName. These transformed attributes will later be used in your match rules.
SemQL Enricher: Normalize First and Last Names
You will now create one SemQL enricher that cleans both names:
- remove punctuation,
- collapse extra spaces,
- trim leading/trailing spaces,
- and apply Proper Case (first letter upper case, others lower case).
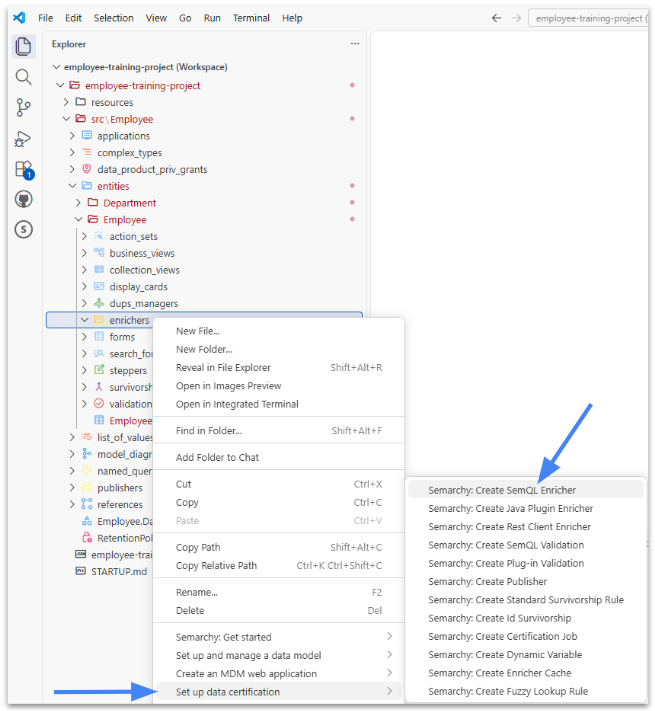
- In entities/Employee/enrichers, run Set up data certification -> Semarchy: Create SemQL Enricher.
- Name it NormalizeNames.
- Open NormalizeNames.SemQLEnricher.seml and observe the default properties:

- Complete the following properties:
label: Normalize first and last names
description: >
  Remove punctuation and extra spaces, then set the first letter upper case and the rest lower case for FirstName and LastName.

entity: Employee.entities.Employee.Employee
enricherExecutionScope: PRE_CONSO

semQlEnricherExpressions:
  - attributeName: FirstName
    expression: INITCAP(
                  REGEXP_REPLACE(
                    LOWER(LTRIM(RTRIM(FirstName))),
                    '[[:punct:]]',
                    ' ',
                    'g'
                  )
                )

  - attributeName: LastName
    expression: INITCAP(
                  REGEXP_REPLACE(
                    LOWER(LTRIM(RTRIM(LastName))),
                    '[[:punct:]]',
                    ' ',
                    'g'
                  )
                )
What this does:
- LTRIM, RTRIM removes leading and trailing spaces.
- LOWER converts everything to lower case.
- REGEXP_REPLACE(..., '[[:punct:]]', ' ', 'g') replaces punctuation with spaces (so "O'Neil" becomes "O Neil").
- INITCAP then capitalizes the first letter of each word and keeps other letters lower case ("o neil" → "O Neil").
- Check Your Work
- Save and close the enricher file.

- Open the Problems tab and confirm there are no errors related to the new attributes.

- Optionally, collapse each enricher block for easier navigation.

Result
You now have clean, consistently formatted versions of FirstName and LastName.
These attributes provide robust inputs for the match rules you'll configure later to detect potential duplicate employees.
Data validation rules ensure that incorrect or incomplete data cannot be entered or imported into the hub. Some checks are built in—like mandatory fields or list-of-values restrictions—while others must be defined explicitly, such as SemQL validation rules and match rules.
In this section, you will discover how to use SemQL for data validation, in order to ensure data consistency.
Add a SemQL Validation
You will create a rule to ensure that an employee's last name is of sufficient length.
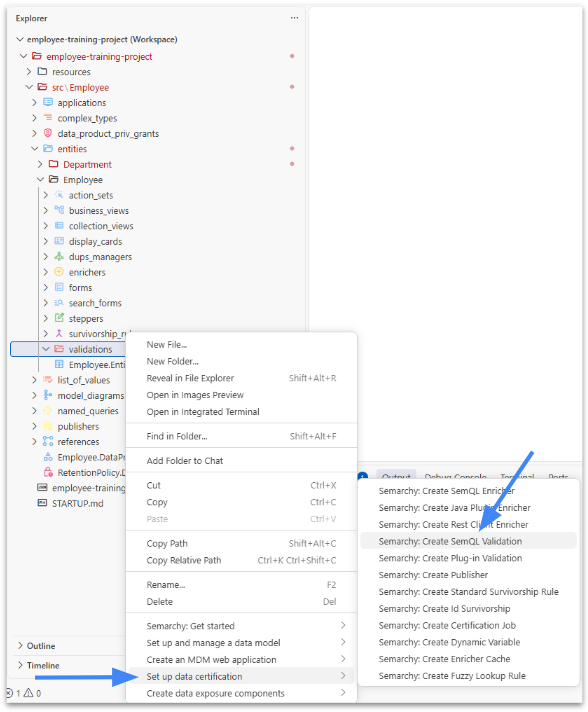
- Create a new validation rule by selecting the Employee > validations folder to use the context command Set up data certification -> Semarchy: Create SemQL Validation:
- At the prompt enter the SemQL Validation name: CheckEmployeeNameLength
- In the entity property, start typing Employee then accept the suggestion
Employee.entities.Employee.Employee
- In the file CheckEmployeeNameLength.SemQLValidation.seml complete the the following properties:
label: Check Employee Last Name Length
condition: length(LastName) > 1
validationScope: PRE_CONSO
What this does:
- The SemQL function LENGTH counts the number of characters in the string
LastName. If the count is greater than 1 then the condition is true, the validation is passed. Otherwise the condition resolves to false, resulting in the rejection of the invalid record. - Validation Scope - PRE_CONSO - Applies to data from all publishers after Enrichment but before Consolidation
- Save and close the validation file.
Match Rules
In this section, you will configure the match rules that will apply to your application. You will learn:
- Understanding the basics of matching
- Creating your first match rule
In Semarchy DM, matching is performed on master records coming from source systems. It is a fundamental step of the certification process that aims at consolidating these master records into unique golden records.
In the case of fuzzy-matching entities, such as the Employee entity, master and golden records use different identifiers:
- Master records are referred to by their IDs in source systems.
- Golden records use IDs generated as defined in your entity.
Match rules define how incoming source records match together. You have full control of the rule details and the thresholds defining when matched records should merge and when merged records should be confirmed.
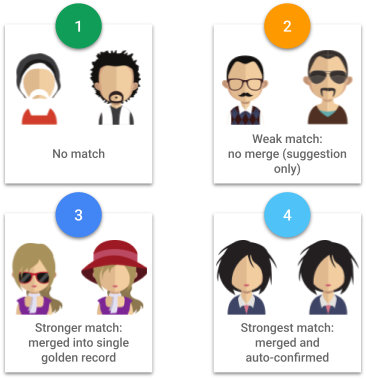
Once master records have been matched, survivorship rules define how their attributes will consolidate into the resulting golden record
To enhance the matching process, you will implement multiple match rules and assign confidence scores.
Configure match rules
You are now going to add a match rule that will leverage the enriched names you added previously.
Add a match rule for standardized Employee names
- Open the existing Employee entity file. In place of the blank NewRule placeholder replace it with ExactNameAndSameSubsidiary.
- Complete the the following properties:
matchRules:
  - _name: ExactNameAndSameSubsidiary
    _type: SemQLMatchRule
    condition:
      Record1.FirstName = Record2.FirstName
      AND
      Record1.LastName = Record2.LastName
      AND
      Record1.Salutation = Record2.Salutation
      AND
      Record1.Subsidiary = Record2.Subsidiary
    label: Match On Name And Same Subsidiary
    matchScore: 100
    usingMatchOn: false
What this does:
- The match rule specifies the condition to consider whether two records are a match or not. It resolves to either a true or a false.
- This is a rule with a high confidence score when two records match, so set the highest possible score of 100.
Add a second match rule for Email
You are now going to add a second match rule. By defining multiple match rules, the matching can be improved. This rule will enhance matching by including email and then assigning a distinct confidence score
- In the Employee entity file, collapse the first match rule and paste in the following properties:
  - _name: ExactNameAndSameEmail
    _type: SemQLMatchRule
    condition:
      Record1.FirstName = Record2.FirstName
      AND
      Record1.LastName = Record2.LastName
      AND
      Record1.Email = Record2.Email
    label: Match On Name And Same Email
    matchScore: 90
usingMatchOn: false- The matcher now looks like this:

What this does:
- This is a less strict rule and will capture those records where the salutation or subsidiary may be missing but have an email, so set a score to 90.
Auto-Confirm Policies and Merge Thresholds
In the same Employee Entity file scroll down to the matcher section. With your two match rules, a confidence score of 100 means an exact match on name and subsidiary, and 90 means a match on name and email alone.
By default, Semarchy already configures the policy so the high-confidence matches merge and confirm automatically, while the lower-confidence email matches still merge but wait for a data steward to confirm. Without changing anything, your matcher section already includes the following:
mergeThresholdRemergingPreviouslySplit: 100
  autoConfirmGoldenThreshold: 99
What this does: with every mergeThreshold property still at 0 except mergeThresholdRemergingPreviouslySplit, any matching records merge automatically. autoConfirmGoldenThreshold: 99 means only match groups scoring 99 or higher — the exact matches found by ExactNameAndSameSubsidiary (score 100) — are confirmed automatically.
Groups matched only by the lower-confidence ExactNameAndSameEmail rule (score 90) still merge, but remain unconfirmed match suggestions for a data steward to review. mergeThresholdRemergingPreviouslySplit: 100 means a golden record group a steward has previously split only re-merges with the steward's involvement, not automatically.
Declare Publishers
Publishers are applications that provide source data to the Data Hub. They are commonly used in survivorship rules, but can also be used in match rules or enrichers.
In this section, you will define three publishers: one for each source system that will supply data:
Payroll, ATS, HR
Create Publishers
- Select the publishers folder, right click and use the context command Semarchy: Create Publisher. Enter the Publisher name Payroll and press Enter

- Use code with value PAY
- Fill in the label with value Payroll
- For property active set to true
- See that the Payroll.publisher.seml file has the following properties and values:
_package: Employee.publishers
_name: Payroll
_type: Publisher
code: PAY
label: Payroll
active: true - Repeat the previous steps to create two other publishers with _name: HR and ATS and with the following codes and labels respectively:
- HR - HR
- ATS - Applicant Tracking System

Define Survivorship Rules
Survivorship rules determine the best value for the golden record from multiple source records that match and merge. A default rule was created automatically with the entity.
You will edit this rule to define the level of trust you place in each of your publishers. This strategy involves manually prioritizing publishers and is widely used, particularly for fields where one source system serves as the system of record for that item.
- To configure the default survivorship rule, go to entities > Employee > survivorship_rules and select the file DefaultRule.StandardSurvivorshipRule.seml. See that the defaultRule is set to true.

- Go to the consolidationStrategy property and change it from
CUSTOM_RANKINGtoPREFERRED_PUBLISHERto select and order your publishers manually.
- Configure the
publisherRankingsin this order:
- HR
- Payroll
- ATS
by setting _type to ConsoPublisherRanking and assigning the publisher
publisherRankings:
  - _type: ConsoPublisherRanking
    publisher: Employee.publishers.HR
  - _type: ConsoPublisherRanking
    publisher: Employee.publishers.Payroll
  - _type: ConsoPublisherRanking
publisher: Employee.publishers.ATS- In the case of a tie, use the following expression to get the most recent record
consolidationOrderByExpression: UpdateDate DESC- Next you'll add the override strategies for the default survivorship rule.
Configure Override Strategies
In this chapter you will learn how attribute values are consolidated and how to allow, or prevent, user-entered values from overriding the consolidated value.
We will continue editing the DefaultRule.StandardSurvivorshipRule.seml file.
In the Employee application, the HR team is responsible for all the attributes. Data stewards are allowed to override them. However, if the HR team provides an updated value, their input should take precedence once again. Hence, you will employ the Override - until consolidated value changes strategy.
- By default, the overrideStrategy property is set to NO_OVERRIDE. Change this property value:
overrideStrategy: UNTIL_CONSOLIDATED_VAL_CHANGE- The default rule should match this sample here:

Configure the hire date survivorship rule
For the hire date attribute, you'll implement a rule that takes the earliest date from the source records.
- Select the survivorship_rules folder, right click and use the context command Semarchy: Create Standard Survivorship Rule. Enter the rule name HireDateRule and press Enter
- In the entity property, start typing Em, to accept suggestion Employee.entities.Employee.Employee

- Fill in the label property:
label: Hire Date Rule- Set value to false for the following properties
defaultRule: false
consolidationSkipNulls: false- For the earliest hire date, you can use the smallest value. End users will not be able to override this consolidated value, so set the following properties:
consolidationStrategy: SMALLEST_VALUE
overrideStrategy: NO_OVERRIDE- Take a look at the PROBLEMS tab, which indicates that an attribute must be specified:

- Start typing
attributesand choose the appropriate attribute value:
attributes:
- attributeName: HireDate- Your survivorship rule file should look like this:

In this chapter, you will generate the Application Components for both the Department and Employee entities.
These components define how your data appears in the Semarchy Data Platform application:
- Display Cards
- Business Views
- Collection Views
- Forms
- Duplicate Managers
- Steppers
- Action Sets
Once created, you'll be able to navigate and edit your Employee and Department data through a complete, ready-to-use application UI.
Create Application Components for the Employee Entity
- In VS Code, right-click the file Employee.Entity.seml and select: Create an MDM web application -> Create application components:
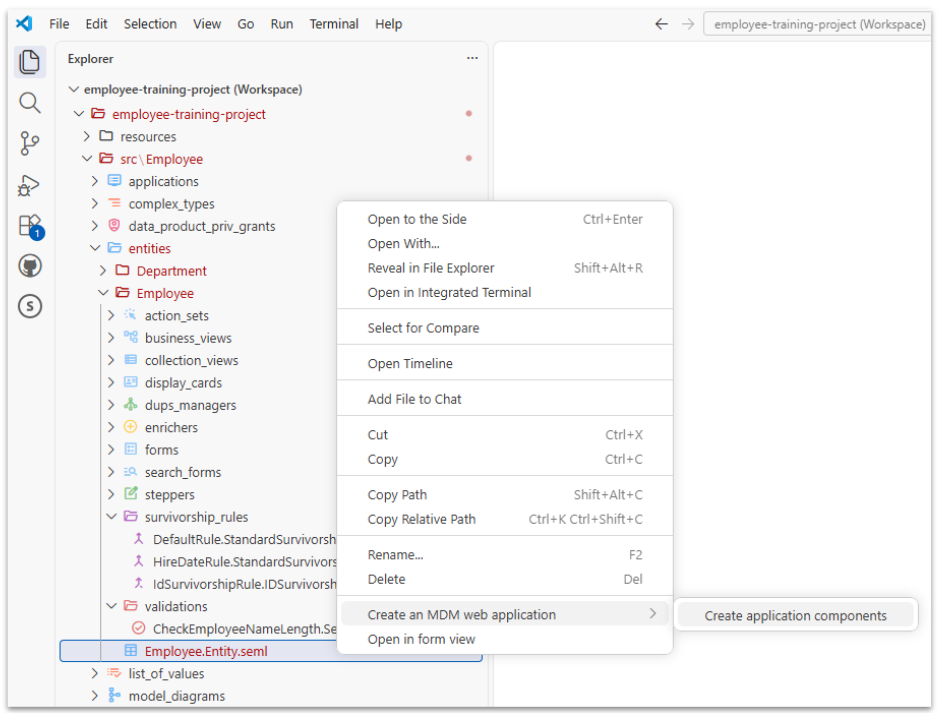
- The command will generate a set of component files under: src/Employee/applications/Employee
You should now see subfolders like:
- action_sets
- business_views
- collection_views
- display_cards
- dups_managers
- forms
- steppers
Each of these will contain a .seml file pre-populated with default properties.

Review the Generated Components
Let's briefly explore what has been created.
- Action Set: Defines the actions available for this entity in the UI (create, edit, delete).
Look at EmployeeActionSet.ActionSet.seml. You'll see actions such as:
- CreateAction
- EditAction
- ImportAction
- MassUpdateAction
- DeleteAction
- ExportAction, etc.
Open EmployeeActionSet.ActionSet.seml. Scroll down to the property ImportAction. Change the importedRecordType from GOLDEN to MASTER:
_type: ImportAction
_name: ImportAuthorEmployees
label: Import
useCustomLabel: true
waitDialogEnabled: false
importedRecordType: MASTER
importMode: CREATE_AND_UPDATE
allowOtherPublishers: true
stepper: Employee.entities.Employee.steppers.AuthorEmployees
This will enable the import of master records instead of golden records. The other actions can be customized later, but their defaults are sufficient for now.
- Business View: Defines how employees appear at the root of the application.
Open EmployeeBusinessView.BusinessView.seml. Check the label property. If the extension didn't generate one automatically, add:
label: EmployeeThis name will appear in the application's left navigation menu.
You may see the warning "A display card is recommended":

If it happens, add:
displayCard: Employee.entities.Employee.display_cards.EmployeeDisplayCardSave and close the file.
- Collection View: shows a list of employees, including filters and visible columns.
Open EmployeeCollectionView.CollectionView.seml. All attributes are visible by default, including technical ones.
These columns can be customized or hidden later.
- Display Card: defines how a single record is displayed (the "details" page).
Open EmployeeDisplayCard.DisplayCard.seml. By default, the generated card shows:
- Primary text: the EmployeeID (converted to text);
- Image placeholder: a centered image using the Picture attribute if available;
- Fallback settings: a default icon when no picture is provided;
- Standard alignment and sizing: FIT mode with centered alignment.

You can later customize this card to show a more user-friendly identifier, such as FirstName + LastName, or display the employee's real picture.
- Forms: control how you create or edit records.
Open: EmployeeForm.Form.seml. The default form includes all entity attributes in a simple layout.
Later, you can group fields, reorder them, or hide technical fields.
- Steppers: enable guided data-entry flows (multi-step forms).
Open AuthorEmployees.Stepper.seml. For now, the default stepper contains a single step.
You'll enhance this later if your application requires structured workflows.
- Duplicate Manager: lets data stewards review, merge, and split groups of matching records, including overriding golden record values.
Semarchy generated ManageDuplicatesOnEmployee.DupsManager.seml for you, already wired to the Employee display card, form, and collection view you just reviewed. Duplicate managers are only generated for fuzzy-matched entities, which is why Department — a Basic Entity — has no duplicate manager.
Create Application Components for the Department Entity
Repeat the same steps for Department.Entity.seml:
- Right-click the file Department.Entity.seml and execute Semarchy: Create Application Components
- Review the generated components under: src/Employee/applications/Department
These components, as for the Employee entity, support browsing, editing, and managing departments within the application.
Quick Validation
Once both entities have their components:
- Check the Problems tab → there should be no new errors.

- Ensure both Business Views have labels.
- Ensure UI components (forms, display cards, views, action sets, steppers...) were successfully generated for:
- Department entity;
- Employee entity.
If both folders are present and contain the expected SEML files, it means your model has no missing essentials and you can proceed confidently to the Build & Deploy chapter.
Result
You now have a complete set of UI components automatically generated for your model.
These components define how users will browse, view, and edit data in your Employee application.
In the next chapter, you will build and deploy your Data Product, and then open your first version of the Employee application in the Semarchy Data Platform.
First, configure the Semarchy Data Platform extension for deployment of the Employee Data Product.
Configure Extension Settings
Configure the extension to connect to your target Semarchy Data Platform instance. In the Semarchy Data Platform extension settings, select the Workspace tab and configure the deployment properties below:
- Optional: Set the API Key. For guidance on obtaining an API key, see Get API Key.

- Then set the Data Location and the Datasource with the following values:
- Data Location: EmployeeMDM
- Datasource: datasource1 (for example)
The Datasource is the name of any existing datasource used to establish the connection to the database. Consult with your platform administrator for a suitable datasource to use.

- Set the Instance URL of your organization's tenant in the format
https:// - Set the Overwrite Deployment URL of your organization's tenant in the format
https:///dpc - Click Authenticate now to sign in to the configured SDP instance. Authentication allows the Semarchy extension to connect to the platform and perform operations such as building and deploying your Data Product.
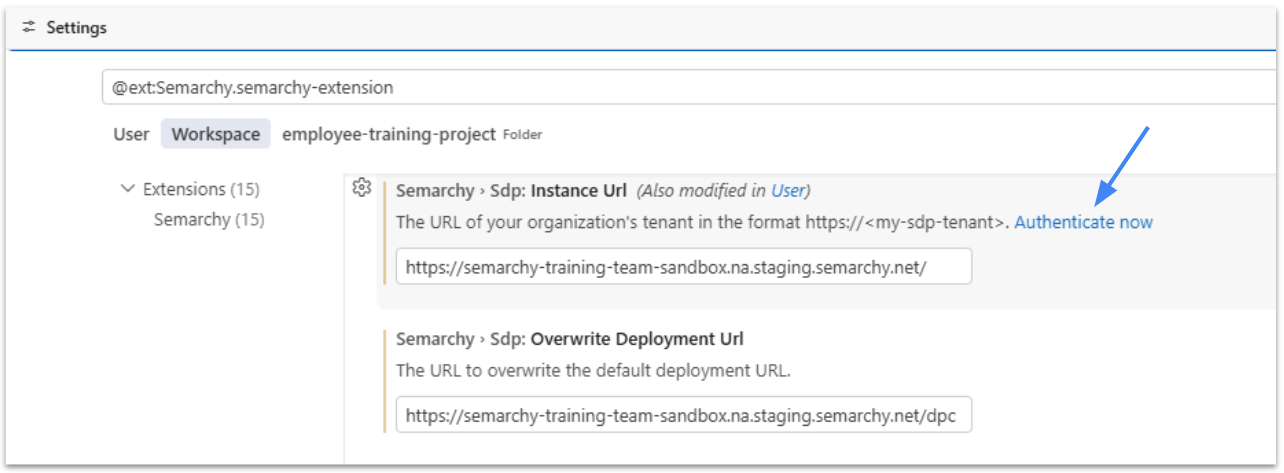
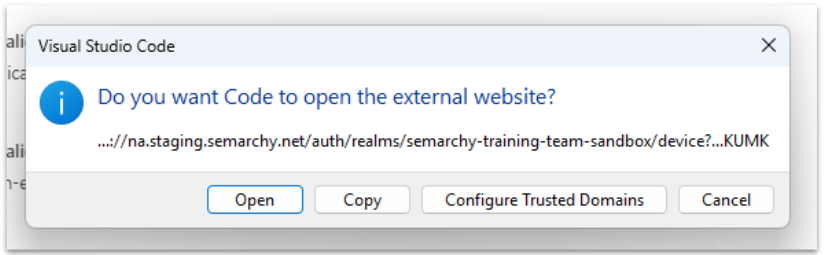
- Click Open to continue the authentication process in your web browser. VS Code opens the configured SDP authentication page, where you can sign in to your instance.
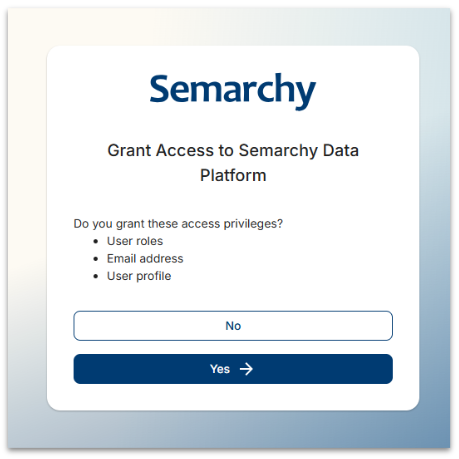
- Click Yes to grant the Semarchy Data Platform access to your user information and complete the authentication.
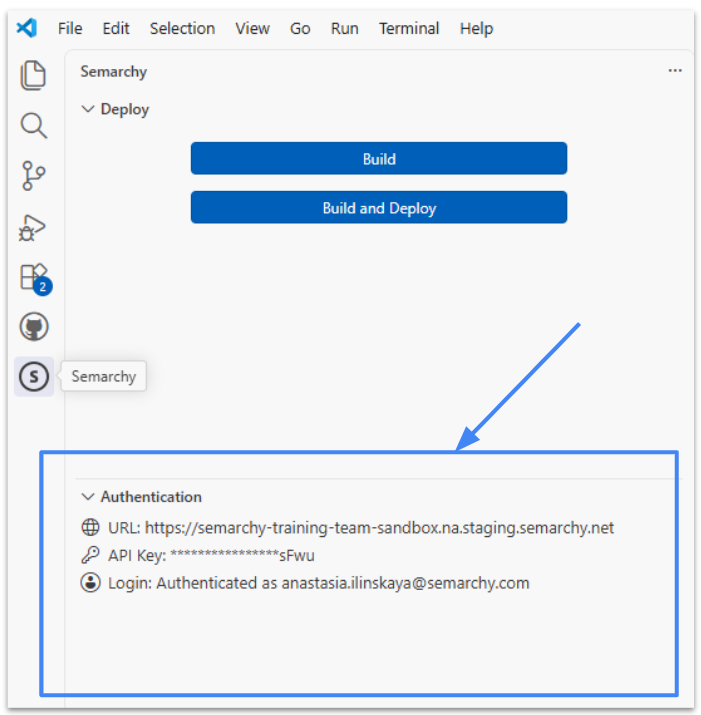
- Expected result: Once authentication is complete, the Authentication section displays the configured SDP instance URL and confirms that you are authenticated with your user account. This authentication is required for the Semarchy extension to connect to the SDP instance and deploy your Data Product.
Checking the Data Product Profile
Before deployment, Semarchy validates the Data Product design and uses Employee.DataProductProfile.seml for its technical configuration.
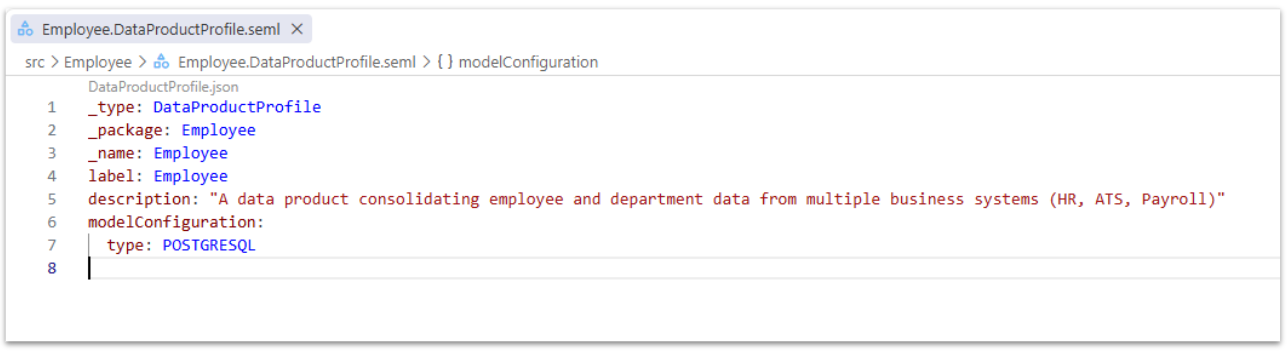
You have already reviewed this file earlier in the tutorial. The profile is required for every Data Product and defines its technical environment.
During validation, build, and deployment, the profile provides configuration such as the target database platform. The logical data model itself is defined by the collection of entity, reference, rule, and other SEML design files in the Data Product.
Build and Deploy Your Data Product
Before deploying your Data Product, validate it for errors and inconsistencies. Validation checks individual design files, while the build verifies that the SEML files work together correctly and generates the deployment payload.
- In the Activity Bar, select Semarchy view and click the Build button

- Resolve any issues you see in the PROBLEMS tab.
- Once you have resolved all the validation issues you are ready to deploy

- Click on the Build and Deploy button
- You can review the build results in the OUTPUT view.
Duration: 08:00
After a successful deployment, sign in to the Semarchy Data Platform and open the deployed Data Product to access its application.
- On the Welcome page find your application in the Data products section.
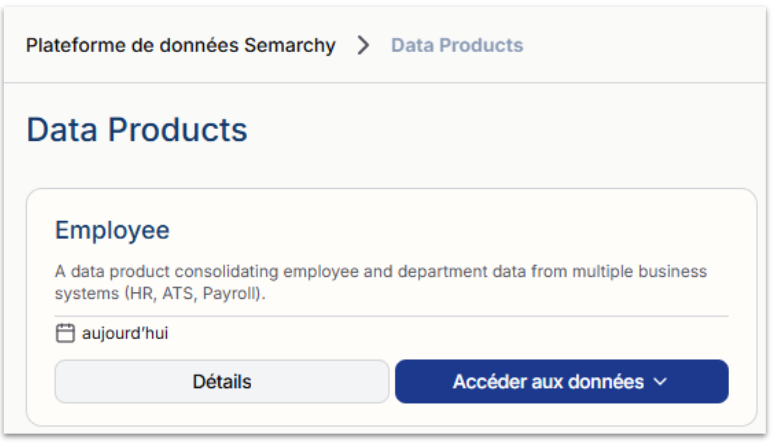
- Click into it and view your application. It might look something like this:

Import and Explore Sample Data
Now you will import data and view it in your application.
- In your application go the Entities folder > Golden Data > Department
- In the menu choose Import and browse to the location of the Department.xlsx file from the tutorial resources you downloaded earlier

- Review the import contents and click Continue.

- Follow the on screen steps and keep the default mappings and click Continue.

- Review the import summary and then click Finish to import the data. The data is submitted to the certification process.
- Wait until the toaster in the bottom left hand corner indicates "Changes successfully applied.", and then select Click to Refresh to see the data.

- The Departments collection is now showing six records:

Import Employee Data
Now you will import the Employee data and view it in your application.
- In your application go the Entities folder > Master Data > Employee
- In the menu choose Import and browse to the location of the Employee.xlsx file from the tutorial resources you downloaded earlier.
- Repeat the previous steps to import employee data. Follow the on screen instructions to
- Review the import contents
- Define and confirm mappings
- Review import summary and click Finish
- When the toaster indicates "Changes successfully applied", click on Refresh to see the imported master data. Note the number of master records imported.
- In your application go to the Entities folder > Golden Data > Employee. Observe that the number of golden records created - compare this to the number of master records, which means that some records matched and merged according to the match rules you defined.

Duration: 02:00
In this tutorial, you explored the Semarchy Data Platform Extension — a Visual Studio Code integration that allows you to design, validate, build, and deploy complete Data Products directly from your development environment.
By building the Employee Data Product and its MDM web application, you learned how to translate business requirements into a structured, governed logical data model.
You designed entities, attributes, and relationships; created enrichers and validations; defined match and survivorship rules; and finally built and deployed your model to the Semarchy Data Platform.
Throughout this experience, you discovered how the extension simplifies the modeling process, increases productivity, and gives developers and data stewards a unified workspace for managing every aspect of the data lifecycle.
What You've Covered
By completing this tutorial, you have learned to:
- Set Up Your Environment:
Install and configure the Semarchy Data Platform Extension in Visual Studio Code.
Create a data project, Data Product package, and Data Product folder using the SDP workspace structure.
- Design and Structure a Logical Model:
Build and configure entities such as Employee (fuzzy-matched) and Department (basic).
Define attributes, relationships, and metadata to represent your business domain.
- Create Reusable Components:
Implement Lists of Values to ensure standardization and data consistency.
- Enhance and Control Data Quality:
Add SemQL Enrichers to clean and normalize data.
Define a Unique Key on the Department entity and a SemQL Validation on the Employee entity to enforce integrity before and after consolidation.
- Configure Matching and Consolidation:
Design Match Rules using normalized comparisons.
Apply Merge Thresholds and Auto-Confirm logic to generate golden records.
- Define Data Sources and Survivorship Logic:
Add and prioritize Publishers (HR, ATS, Payroll).
Create Survivorship Rules that determine how final golden values are chosen.
- Deploy and Explore the Application:
Configure deployment settings, validate and build the Data Product, deploy it, and import sample data.
Access the application through the Semarchy Data Platform and validate your results.
What's Next
Now that you've built and deployed your Employee application, you can continue practicing by exploring more features on your own. Try adding new attributes or LOVs, refining your match rules, customizing forms and views, or loading additional sample data to test how your application behaves with real-world scenarios.
We will also be releasing new tutorials soon, covering advanced UI configuration, workflows, integrations, and more. Stay tuned for the next steps in your learning journey!